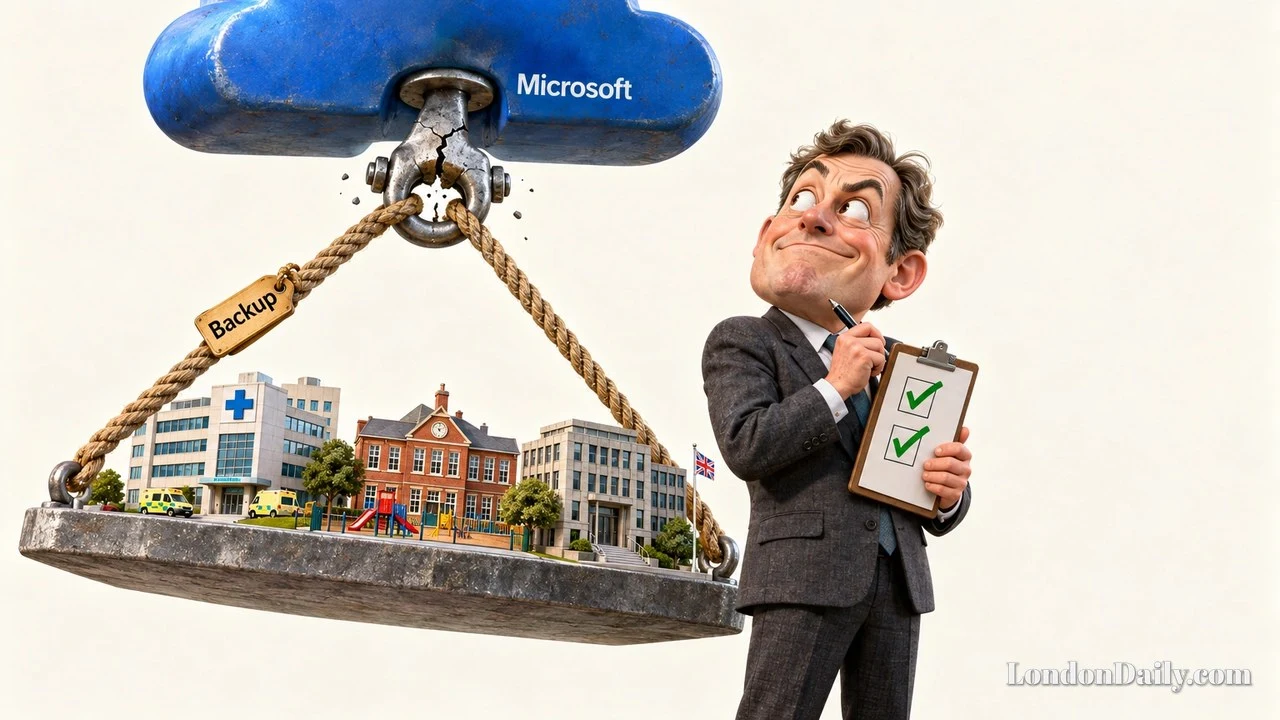
Microsoft’s cloud outage exposes the cost of Britain’s dependence on a shared supplier: services with different names and different responsibilities can become unavailable together because they rely on the same underlying systems. The Internet does not need to go down for much of public life to seize up.
The disruption spans Microsoft services including Outlook, Teams and Microsoft 365, alongside Microsoft-dependent systems in hospitals, GP practices, pharmacies, schools, universities and businesses. Government and parliamentary email and internal systems are affected, as are some police online reporting services. These are distinct organisations. Their exposure to failure is not nearly so distinct.
Microsoft reports a cascading server-capacity failure across its global cloud network. The precise initiating cause remains unconfirmed; a configuration problem is one possibility. The reported mechanism involves overloaded secure-connection and access processes, servers becoming unresponsive or failing health checks, and the remaining servers taking on more demand. Capacity disappears, pressure rises, and the failure spreads.
That distinction matters. This is not evidence that the worldwide Internet has a central off switch. It is evidence that essential services can acquire a common point of failure through the infrastructure they choose to share.
The Internet’s underlying design allows traffic to take alternative routes where those routes and sufficient capacity exist. But another route cannot restore an application whose cloud service or access system has stopped working. A functioning road network is little consolation if every destination has locked its doors.
Nor is a backup necessarily an escape route. If it depends on the same faulty software, configuration or authentication process, it may reproduce the failure rather than survive it. Counting copies is not the same as establishing independence.
The practical response should therefore be more demanding than a promise to restore service and review procedures. Critical organisations need to establish which functions can continue when their principal supplier cannot. For health, banking, transport and emergency services, that means protected, segmented systems, controlled updates and rehearsed recovery arrangements with clear responsibilities and communication routes.
Safer updates matter too: pilot deployments, small-group releases, real-world testing and independent checks before changes spread widely. Verified backups and tested rollback procedures should make recovery an operational capability, not an aspiration.
Supplier diversity has a purpose beyond collecting more contracts. Alternative platforms and open, interoperable standards are useful only if essential work can actually move between them. An alternative that has never been tested under outage conditions is still a proposition, not a demonstrated fallback.
None of this requires pretending that every organisation must abandon Microsoft. It requires refusing to confuse reliance on a large supplier with resilience. The standard for essential services should be brutally practical: when that supplier fails, what still works?
Join the conversation