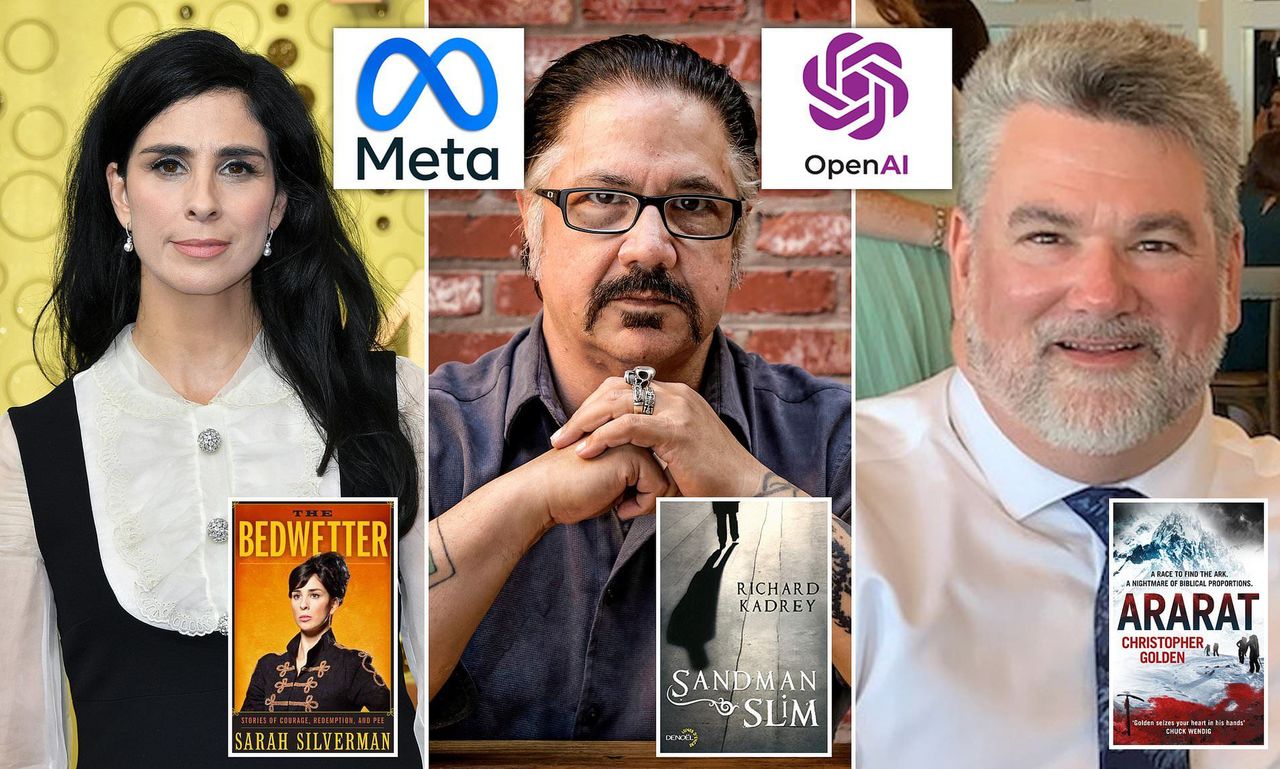
U.S. Comedian Sarah Silverman, in conjunction with famed authors Christopher Golden and Richard Kadrey, has initiated legal proceedings against tech giants OpenAI and Meta, alleging copyright infringement. According to The Verge, the lawsuit filed in a U.S. District Court claims these entities utilized the plaintiffs' copyrighted content to train AI language models without prior consent.
Specifically, the lawsuit alleges that ChatGPT, an AI language model developed by OpenAI, was trained on their copyrighted materials, which they never permitted. The training of ChatGPT entailed ingesting and leveraging a vast amount of textual data, among which the plaintiffs allege their works were included.
In a parallel case, a report by The Guardian elucidates that Meta faces similar charges. The authors claim their copyrighted books were incorporated into the dataset used to train LLaMA, a suite of AI models owned by Meta. LLaMA, serving as a robust language model, forms a cornerstone for AI research and is designed for a wide array of tasks.
According to the lawsuits, the copyrighted works were acquired from a so-called "shadow library", encompassing the texts of thousands of books. The plaintiffs allege that ChatGPT, when prompted, can summarize three notable books: Silverman's 'The Bedwetter', 'Ararat' by Golden, and Kadrey's 'Sandman Slim'. The lawsuit states that ChatGPT failed to reproduce any copyright management information included in their published works.
Legal representatives Joseph Saveri and Matthew Butterick, on behalf of the authors, expressed that since ChatGPT's inception, concerns have been raised by writers, authors, and publishers regarding the tool's ability to generate text bearing striking resemblance to copyrighted material.
Saveri and Butterick are also representing two additional authors, Mona Awad and Paul Tremblay, in a separate class-action lawsuit against OpenAI. The authors claim that ChatGPT was trained on their works without their consent, as reported by The Guardian.
The waves of copyright infringement cases extend beyond textual content. Getty Images has filed a lawsuit against Stable Diffusion, the company behind an AI image generator, alleging a breach of copyright.
Additionally, Saveri and Butterick are representing three artists - Sarah Andersen, Kelly McKernan, and Karla Ortiz - in a lawsuit against image generator companies Stability AI, Midjourney, and Deviant Art.
Both OpenAI and Meta have yet to issue any comments regarding these allegations.
LONDON DAILY ARCHIVE
Sarah Silverman and Renowned Authors Lodge Copyright Infringement Case Against OpenAI and Meta
High-profile figures allege that their copyrighted content was unlawfully utilized to train AI language models.
13 July 2023 · 12:11 UTC